Writing
Write-ups from building this thing. Mostly about checks that cannot report failure.
What these have in common
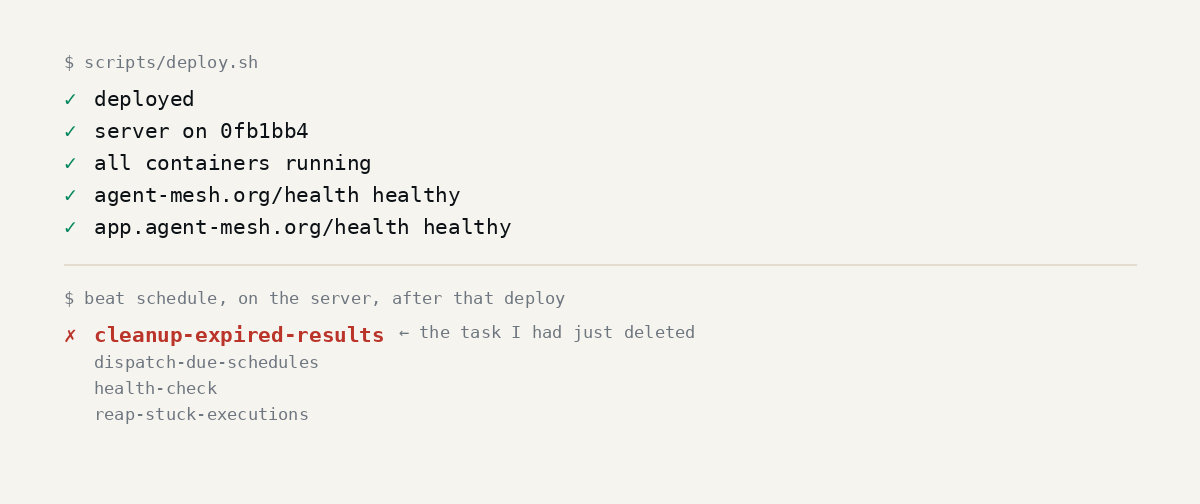
Every one is a failure that reported success. A run that finished COMPLETED having answered from data it never read. A deploy that printed five true green lines over a scheduler running two-week-old code. Twenty-seven workflow branches skipped while every run logged success. None of them threw an error, which is exactly why each one lasted weeks.
They are written from this product's own runs, with the numbers left in. Source: the raw execution record behind the first one is published in full, and three runs are opened up step by step — $0.0144 for a worked support-ticket example, $0.0204 for a real logged run that also escalated, $0.0024 for one that failed early.
| Post | What reported success | What it cost |
|---|---|---|
| A support agent and a refund ticket | A run that answered from two lookups that returned 403 | $0.0204 |
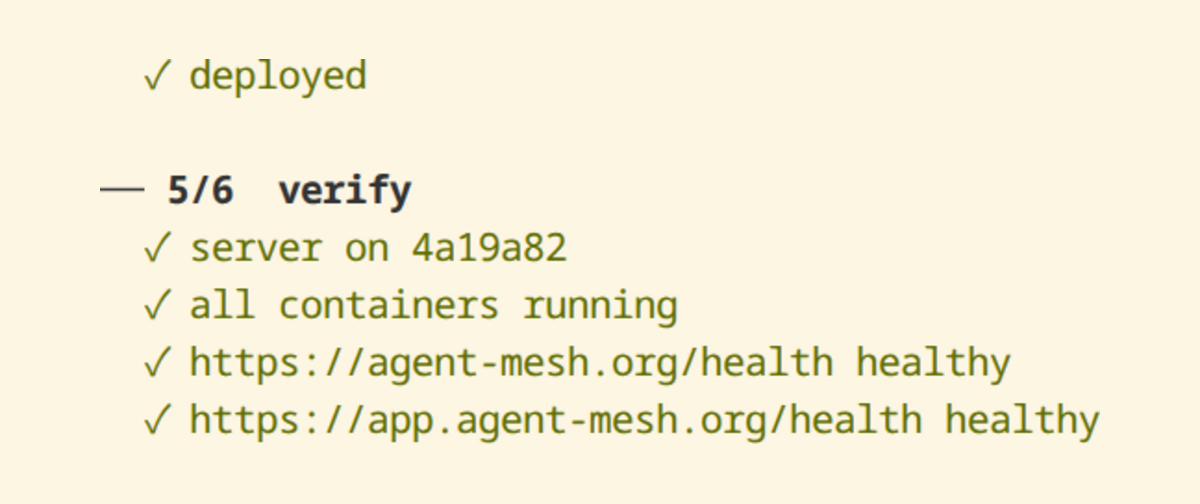
| Every deploy said green | Five true green checks over a scheduler two weeks stale | Two weeks of silent deploys |
| The enum value that had never been written | 27 branches skipped, every run COMPLETED | Weeks, and $0.02 of cost data destroyed by a cast |
The pattern underneath all three
A status only knows whether something threw
Not whether the work happened. Every post here is the gap between those two, and it is the single most expensive thing I have found in this codebase.
A check that cannot report failure is not a check
A health endpoint that answers. A test that acts and never asserts. A cleanup job that logs "removed 0" forever. Each is a green light wired to nothing.
The count is the check
What survives is two-sided: the run says what it processed, the source says what it handed over, and the two have to tie out. A count of zero on a normally busy slot is a signal. A green status is not.
Also published elsewhere
These are the originals. Where a piece is mirrored, the mirror carries a canonical link back here:
- My support agent wrote "I can see you were charged". Both lookups had failed. on dev.to
- My support agent wrote "I can see you were charged". Both lookups had failed. on Hashnode
- Every deploy said green. The scheduler was two weeks behind. on dev.to
- The enum value that had never been written on dev.to
- The enum value that had never been written on Hashnode
- See a real run — the runs these posts refer to, costed step by step
- Help centre — twenty guides on building the thing rather than debugging it
- How to troubleshoot a failed run — the practical version of all three posts